DeepSeek OCR
Visit Website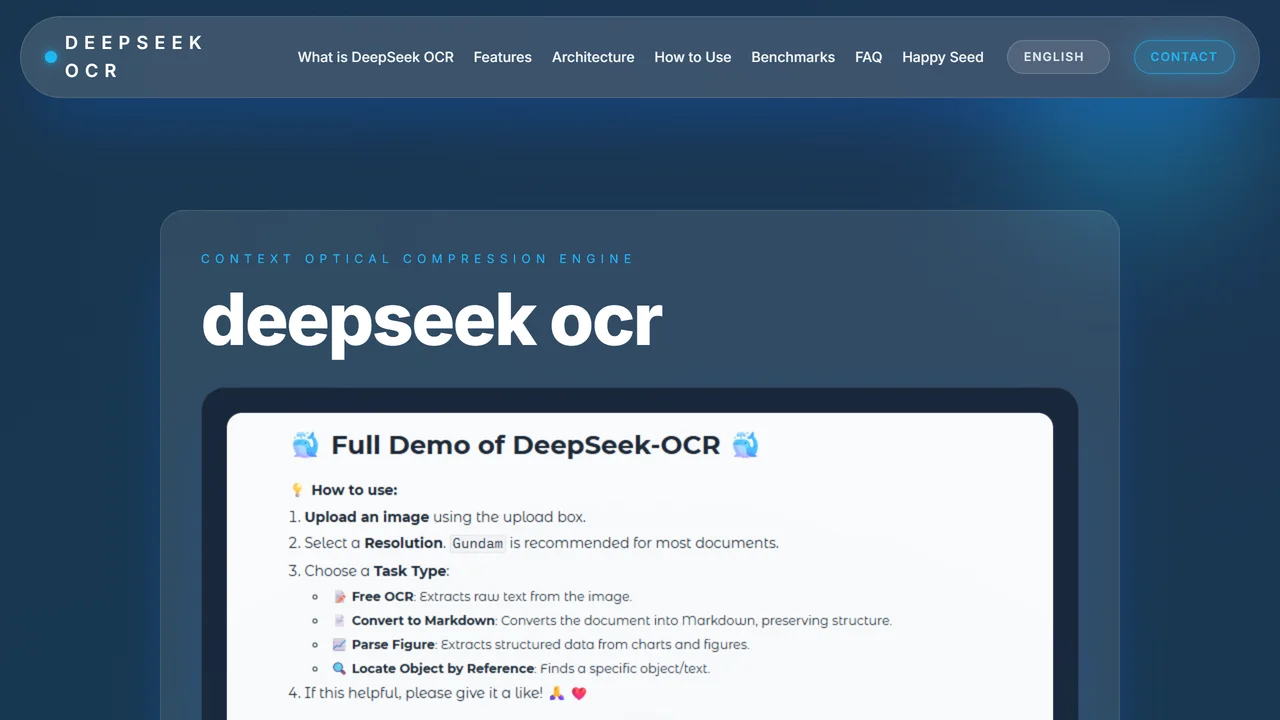
What is DeepSeek OCR?
DeepSeek OCR is a next-generation document intelligence system that leverages a context optical compression engine to deliver state-of-the-art accuracy and efficiency. It compresses high-resolution documents into lean vision tokens, then decodes them with a 3B-parameter mixture-of-experts (MoE) model, achieving near-lossless text, layout, and diagram understanding across 100+ languages. With 97% exact-match accuracy on the Fox benchmark at 10× compression, it outperforms traditional OCR pipelines while drastically reducing compute requirements. The system can process 200,000 pages per day on a single NVIDIA A100 GPU, making it highly scalable for enterprise use.
DeepSeek OCR uses a two-stage transformer architecture. Stage 1 combines a windowed SAM vision transformer with a dense CLIP-Large encoder and a 16× convolutional compressor to convert page images into compact vision tokens. Stage 2 employs the DeepSeek-3B-MoE decoder (with ~570M active parameters per token) to reconstruct text, HTML, and figure annotations with minimal loss. Trained on 30 million real PDF pages plus synthetic charts, formulas, and diagrams, it preserves layout structure, tables, chemistry (SMILES strings), and geometry tasks. Its CLIP heritage maintains multimodal competence, enabling captions and object grounding even after aggressive compression.
Key benefits include multilingual support for Latin, CJK, Cyrillic, and scientific scripts, enabling global digitization and data generation. The system offers scalable model variants from Tiny (64 tokens) to Gundam (multi-viewport tiling), allowing users to balance speed and fidelity. Use cases span legal document processing, financial report analysis, scientific literature extraction, and historical archive digitization. Technical details include 80M-parameter windowed SAM plus 300M-parameter CLIP-Large for aligning local glyph detail with global layout features, ensuring high fidelity in dense PDFs. By reducing a 1024×1024 page to just 256 tokens, DeepSeek OCR enables long-document ingestion that would overwhelm conventional OCR pipelines, keeping global semantics while slashing compute requirements.
Use Cases
Key Features
context optical compression near lossless text extraction 100+ language support 97% exact match accuracy 10× compression ratio 200K pages per day layout structure preservation table and diagram understanding chemistry SMILES decoding MoE model efficiencyWho is it for?
enterprise document teams, data extraction engineers, OCR pipeline developers, digital archivists, compliance analysts, research scientists, multilingual document processors
Similar Tools

Details

DeepRead.Tech is an AI-native OCR platform that achieves over 95% accuracy without any prompt engine...
freemium


Details

GetSearchablePDF is a powerful online OCR tool that transforms scanned PDFs and images into fully se...
Subscription
Details
Scanned.to is an AI-powered OCR tool that transforms scanned documents into perfectly formatted digi...
Free trial