What is turbopuffer?
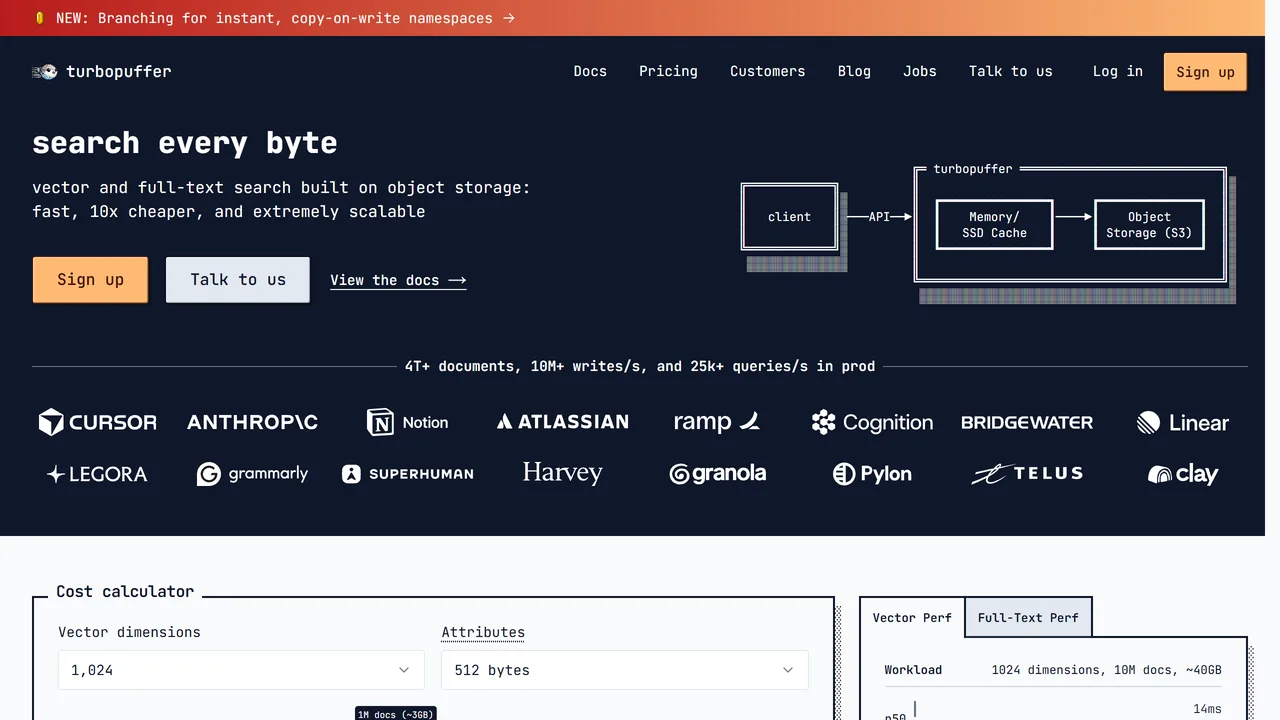
turbopuffer is a revolutionary vector database that drastically reduces the cost of vector search while maintaining exceptional performance. Traditional vector databases often come with high infrastructure costs, especially when dealing with billions of vectors. turbopuffer addresses this by employing advanced indexing and compression techniques, resulting in up to 10x lower costs compared to alternatives like Pinecone or Weaviate. It is purpose-built for AI applications that require fast, accurate similarity searches, such as semantic search, recommendation engines, anomaly detection, and retrieval-augmented generation (RAG). The database supports high-dimensional vectors and offers real-time insertion and querying with low latency. Developers can easily integrate turbopuffer via its RESTful API or SDKs for popular languages. With built-in support for filtering, hybrid search (combining vector and keyword), and horizontal scaling, turbopuffer is a robust solution for both startups and enterprises. Whether you are building a product search for an e-commerce platform or a semantic chatbot, turbopuffer provides a cost-effective, scalable backend that doesn't compromise on quality. Its pricing model is transparent and predictable, starting at $64 for a production-ready tier, making advanced vector search accessible to a wider audience.
Use Cases
Key Features
10x cheaper vector search compared to alternatives Sub-millisecond query latency High-dimensional vector support (up to 4096 dimensions) Real-time ingestion and updates Built-in hybrid search (vector + keyword) RESTful API and SDKs (Python JavaScript Go) Automatic scaling and fault tolerance Metadata filtering and aggregationWho is it for?
AI engineers, machine learning teams, backend developers, and data scientists building applications that require cost, effective and scalable vector search.
Similar Tools
Details

Pinecone Assistant enables developers to create production-grade chat and agent applications in minu...
freemium
Details

Chat With RTX is a free, locally-run AI tool from NVIDIA that allows you to personalize GPT chatbots...
free
Details

SuperExpert AI is an open-source platform designed to simplify the creation and deployment of advanc...
Free
Details

PrivateGPT is an open-source API layer designed to transform local AI models into production-ready a...
Free