What is Miso One?
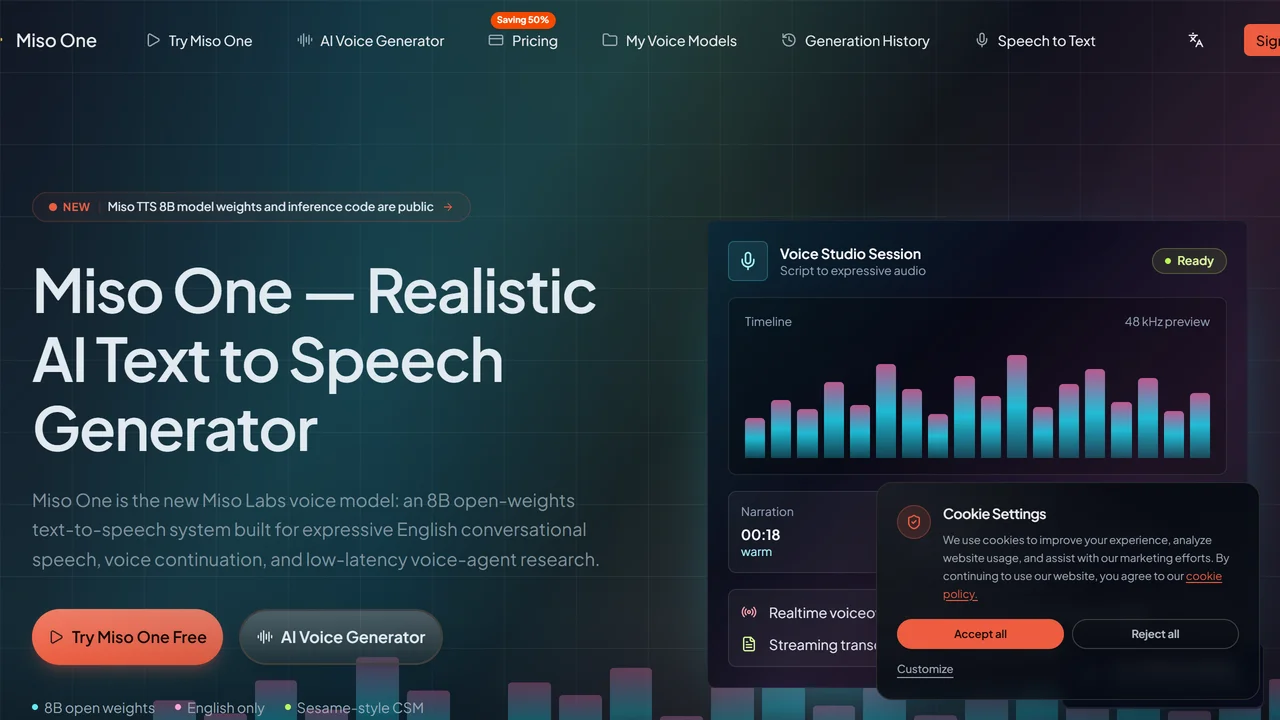
Miso One is the latest open-weights text-to-speech model from Miso Labs, built on the Miso TTS 8B architecture. It is designed for expressive English conversational speech, offering low-latency generation with a published 110 ms latency, making it ideal for real-time voice-agent research and creator workflows. The model supports voice continuation and one-shot voice cloning by conditioning on prompt audio, enabling natural-sounding speech with emotional variation, pacing, and conversational delivery.
Key features include high-quality emotive speech synthesis, low-latency streaming, and support for voice continuation from short audio samples. Miso One excels in use cases such as voice agents, interactive narration, live translation (e.g., English to Spanish), and dynamic captioning. Developers can download the open weights from Hugging Face and run inference locally, though the 8B parameter model requires substantial hardware (e.g., high-end GPU with ample VRAM).
Technical details: Miso TTS 8B is an English-only model, currently lacking multilingual support. It employs a transformer-based architecture optimized for expressive speech and low-latency inference. The model is watermarked to discourage misuse, and users must adhere to responsible voice-cloning boundaries. The repository provides code for inference, fine-tuning, and integration into voice-agent pipelines.
Benefits include realistic, emotionally varied speech that enhances user engagement, low latency suitable for real-time applications, and open access for research and development. Use cases span voice assistants, audiobook narration, game characters, and accessibility tools. Developers should note the hardware requirements and English-only limitation when planning deployments. Miso One represents a significant step forward in open-source TTS, offering state-of-the-art quality for conversational AI.
Use Cases
Key Features
expressive English speech low latency generation voice continuation one shot voice cloning emotional variation conversational delivery open weights model real time voice agentsWho is it for?
voice agent researchers, content creators, developers, AI engineers, interactive narration teams, live translation developers