What is VoiceCraft?
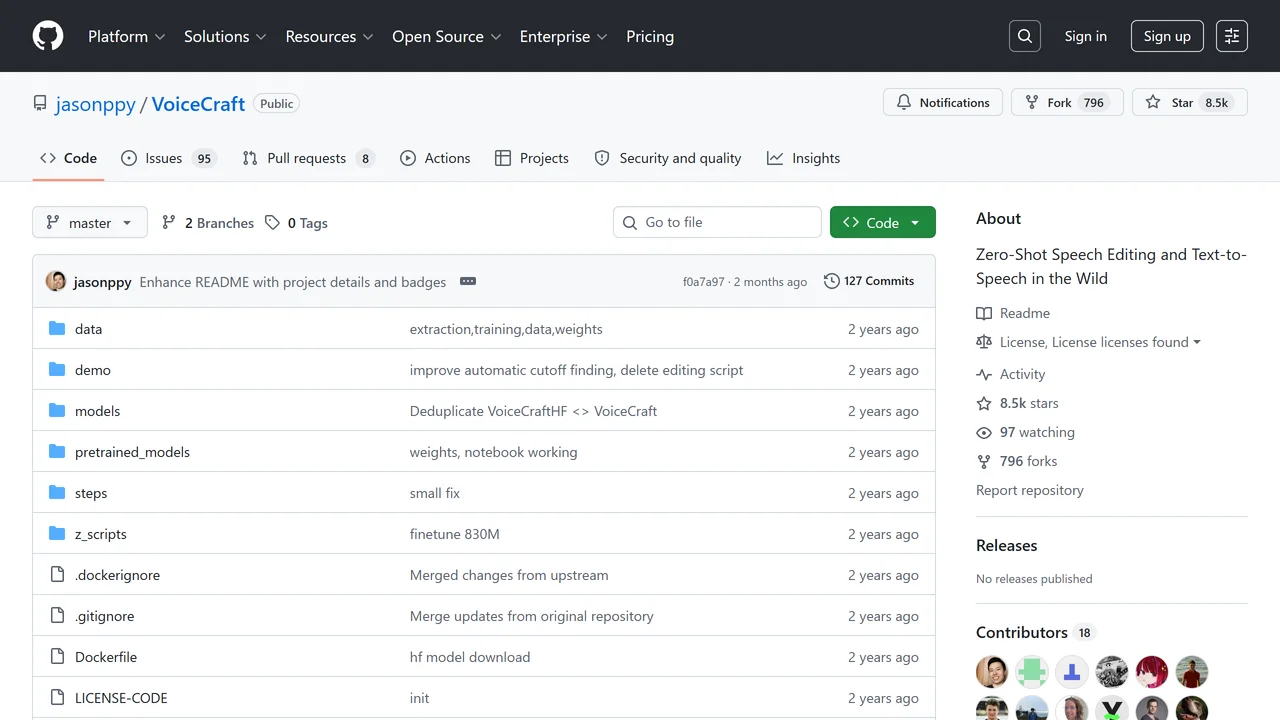
VoiceCraft is a cutting-edge token infilling neural codec language model designed for zero-shot speech editing and text-to-speech (TTS) in real-world scenarios. It achieves state-of-the-art performance on diverse in-the-wild data, including audiobooks, internet videos, and podcasts, requiring only a few seconds of reference audio to clone or edit an unseen voice.
Key features include high-quality speech editing and TTS with minimal data requirements. VoiceCraft can seamlessly edit existing speech by replacing words or phrases while maintaining natural prosody and speaker identity. For TTS, it generates natural-sounding speech from text using a short reference clip, making it ideal for voice cloning applications.
Benefits include significant time savings for content creators, enabling rapid voiceover production without extensive recording sessions. It enhances accessibility by allowing users to generate personalized speech for assistive technologies. The model's zero-shot capability means no fine-tuning is needed for new speakers, simplifying deployment.
Use cases span audiobook narration, podcast production, video dubbing, and voice assistants. For instance, editors can correct mispronunciations in recordings without re-recording, while developers can integrate voice cloning into apps for personalized user experiences.
Technical details: VoiceCraft uses a transformer-based architecture trained on large-scale datasets like Gigaspeech and LibriLight. It employs top-k sampling (k=40) for improved inference quality. Model weights are available in two sizes: giga330M (330 million parameters) and giga830M (830 million parameters), optimized for different performance needs. The maximum prompt plus generation length is 16 seconds for the TTS-enhanced models. The model supports both speech editing and TTS through dedicated scripts (tts_demo.py, speech_editing_demo.py) and interactive Gradio interfaces hosted on HuggingFace Spaces and Replicate. Environment setup requires Docker or manual installation of dependencies, with detailed instructions provided in the repository.
Use Cases
Key Features
zero shot speech editing text to speech synthesis voice cloning minimal reference audio natural prosody preservation speaker identity retention no fine tuning neededWho is it for?
content creators, audiobook narrators, podcast producers, video editors, voice assistant developers, accessibility specialists