What is Whisper?
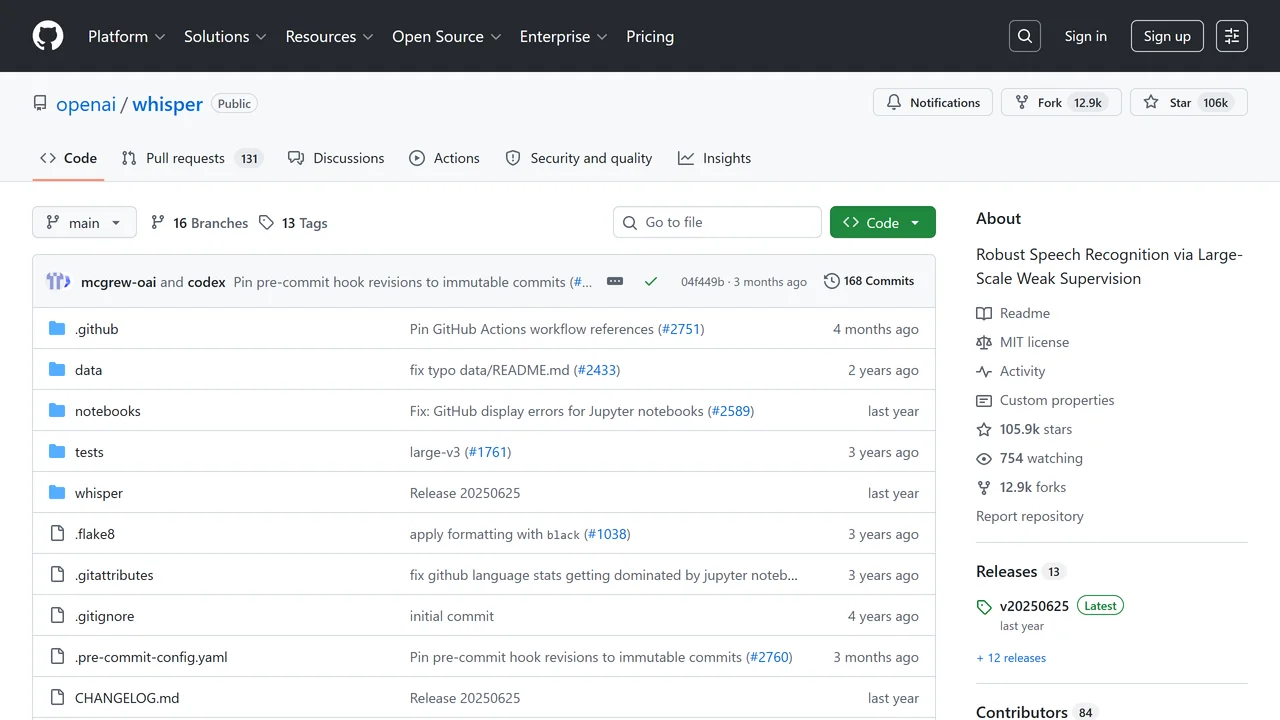
Whisper is a general-purpose speech recognition model developed by OpenAI, designed to robustly transcribe and translate audio across multiple languages. It is trained on a large and diverse dataset of weak supervision, enabling it to handle a wide range of audio conditions, including background noise, accents, and varying recording quality. The model is based on a Transformer sequence-to-sequence architecture, which is trained on multiple speech processing tasks such as multilingual speech recognition, speech translation, language identification, and voice activity detection. These tasks are unified through a set of special tokens that act as task specifiers, allowing a single model to replace multiple stages of a traditional speech-processing pipeline.
Key features include high accuracy in both English and non-English languages, support for real-time and batch processing, and the ability to output transcriptions with timestamps. Whisper offers five model sizes—tiny, base, small, medium, and large—each balancing speed and accuracy. The large model provides the best accuracy but requires more computational resources. The model is open-source and can be run locally, ensuring data privacy and offline capability.
Whisper is ideal for use cases such as transcribing meetings, lectures, podcasts, and interviews; generating subtitles for videos; enabling voice-controlled applications; and assisting in language learning. It also supports speech translation from any language to English, making it valuable for cross-lingual communication.
Technical details: Whisper requires Python 3.8-3.11 and PyTorch 1.10.1 or later. It depends on OpenAI's tiktoken for fast tokenization and ffmpeg for audio processing. Installation is straightforward via pip, and the model can be used through a command-line interface or Python API. The codebase is available on GitHub with a permissive license, allowing customization and integration into various applications.
Use Cases
Key Features
multilingual speech recognition speech translation language identification voice activity detection real time processing batch processing timestamped transcriptions multiple model sizes open source local deploymentWho is it for?
developers, researchers, content creators, transcription services, language learning platforms, accessibility teams, media companies
Similar Tools
Details
Superwhisper is a macOS app that transforms your voice into text with high accuracy, powered by adva...
Freemium
Details

AudioNotesAI is an advanced speech-to-text tool that transforms spoken words into polished, versatil...
Freemium
Details

Voice Note Taker is an AI-powered tool that transforms spoken words into organized, searchable notes...
Freemium
Details

EchoScribe is a cutting-edge AI-powered transcription tool designed to convert audio and video conte...
Free